By Twisha Shah-Brandenburg
Within a few years, most important decisions will arrive with a draft answer attached: strategy options, product roadmaps, hiring decisions, and risk assessments. AI will produce recommendations that look considered before the real thinking begins. They will be fluent, structured, and ready to paste into a deck.
The danger is not that these answers will always be wrong. It is that they will be wrong with confidence. A polished output can conceal a shaky premise and make it easier to move forward than to ask whether the reasoning holds.
Questioning a confident recommendation is not an individual act of courage. It is an organizational capability. Most organizations have never built it deliberately.
AI also removes a signal organizations once relied on: friction. Long debates and uncertain progress often revealed unresolved reasoning. Now, the absence of friction can be mistaken for clarity.
That is automation bias at organizational scale. It is not a cognitive glitch. It is a structural risk.
Why MBO, OKRs, and HEART Don’t Measure What AI-Era Organizations Need
Management frameworks have long asked how to measure organizational performance. MBO focused on results, OKRs made priorities and accountability visible, and HEART asked whether teams improved the customer experience.
These are important measures. None, however, tells you whether the next decision will be smarter because the organization learned from it.
They track whether an organization met an objective, completed work, or improved an experience. They do not preserve the reasoning behind a decision: what the organization believed, what had to be true for the bet to work, or what evidence should have prompted a course change.
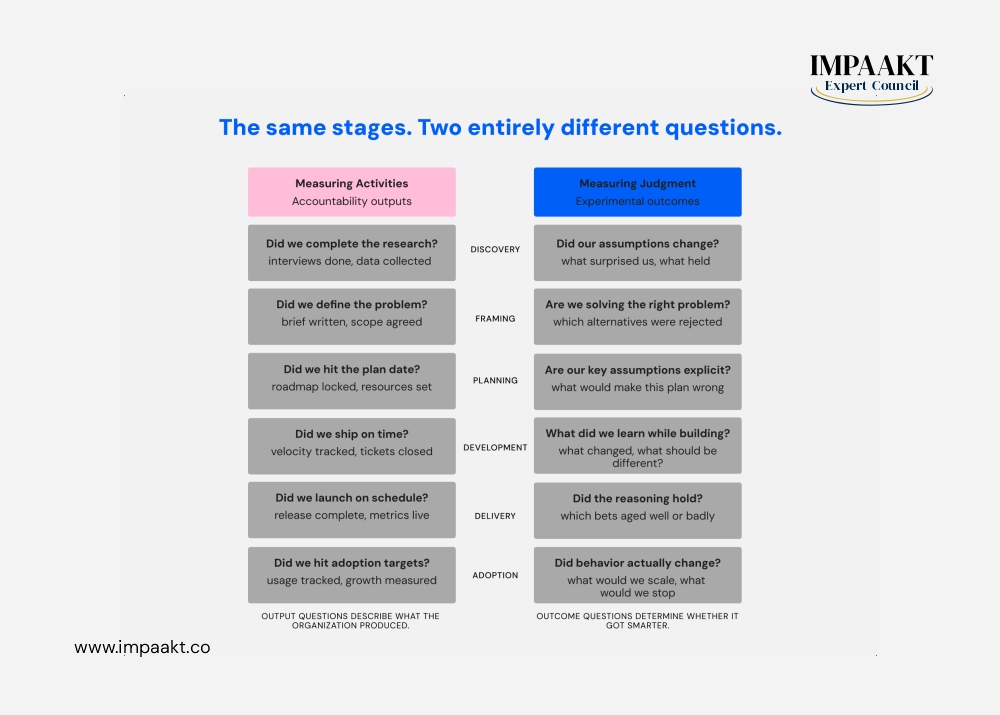
Most organizations measure what was produced: research completed, problems defined, products launched, adoption increased. These are accountability questions.
Judgment questions are different: Did the research change our assumptions? Which conditions held? Which bets aged well? What would we recognize sooner next time?
Most dashboards answer the first set. The second is where the judgment gap lives.
AI makes execution faster and cheaper. The constraint is increasingly clarity: distinguishing a credible recommendation from a persuasive-looking one, and recognizing when its premise is no longer holding. A system that tracks only delivery can signal progress while the organization repeats the same mistake.
Three Places Organizations Stop Getting Smarter
Faster does not mean smarter. Organizations rarely lack insight. They fail because insight does not survive the journey to the decisions that matter.
A customer tells a salesperson, “We’re not using the feature because we can’t trust the data it shows.” By the time it reaches the product team, it becomes: “Adoption friction reported in Q2.” A different team later rediscovers trust as a barrier and treats it as new. The roadmap still prioritizes new features over data integrity. The organization has gathered information. It has not learned.
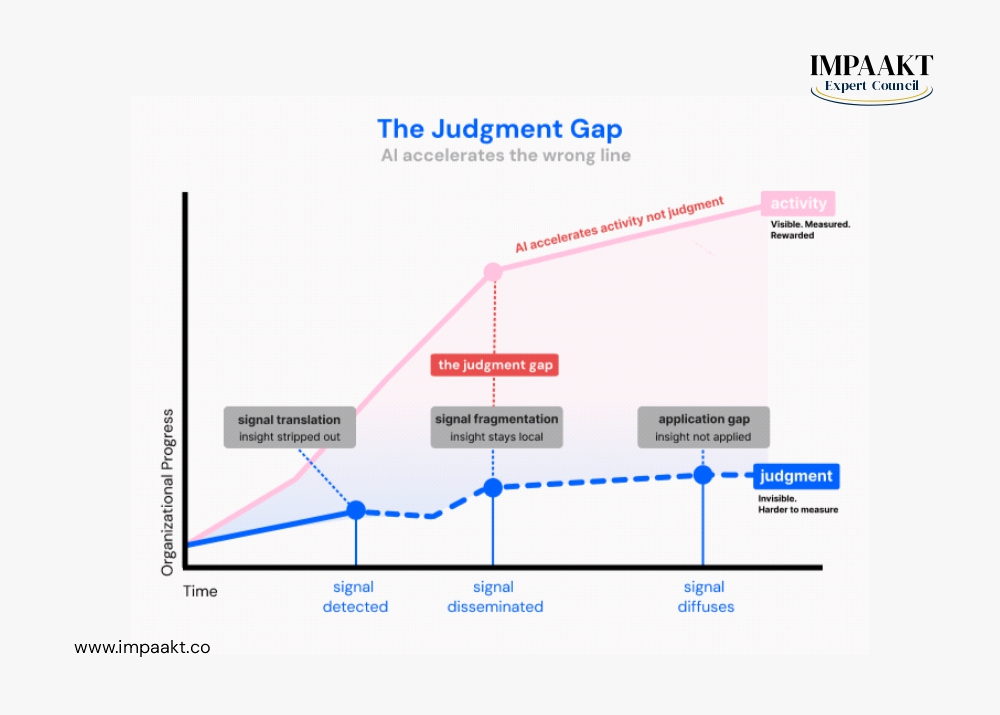
This is how the judgment gap forms. A signal is detected, translated, separated from its context, and disconnected from the decision it should change. The information moves through the organization. The insight does not.
The cycle breaks in three places:
- Signal translation. A clear observation becomes a generalized category in a deck, dashboard, or AI-generated brief. The words travel. The meaning does not.
- Signal fragmentation. Sales hears the concern. Support sees complaints. Product sees declining adoption. Data teams see anomalies. No one holds the full picture long enough to connect it.
- The application gap. The signal reaches the right people but does not change the decision. Timelines, incentives, sunk cost, or confidence in an existing recommendation override it. The organization knows more. It does not decide differently.
AI can intensify each break. It summarizes evidence before decision-makers examine it, produces complete-looking outputs without cross-functional context, and makes questioning a fluent recommendation feel slow.
Medicine and aviation make failure travel forward through case reviews, procedures, and checklists. Most organizations let learning remain local, in a team, a retrospective, or an archived deck. The same mistake returns under a new name and often with a larger budget.
How Do We Close the Judgment Gap?
Closing the judgment gap does not require a new methodology. It requires a shared practice attached to decisions that move real resources.
Before a meaningful commitment, write down three things:
What problem will this solve, and for whom?
Name the user or business problem and the outcome you expect to change.
What must be true for it to work?
Identify the assumptions beneath the recommendation: customer behavior, data quality, operational readiness, incentives, or technical feasibility.
What evidence would cause us to revise, pause, or stop?
Define the signals that would show the premise is not holding, and when they will be reviewed.
Keep these answers visible at the top of a brief, roadmap, or investment memo. This is not a new approval layer. It is a decision record: a compact account of what the organization believed when it chose to act.
Then make the learning travel. In the business review you already run, add one standing question: Which decisions from the last cycle did not hold, and what did we learn from them?
Spend fifteen minutes reconstructing the decision: What did we believe? Which condition failed? What signal did we miss? What will we recognize earlier next time?
Over time, those answers become organizational memory. Teams stop rediscovering the same lesson in different language. The organization does not simply remember what happened. It gets better at deciding.
What Leadership Makes Possible
When a team says, “We should stop this project because the premise is not holding,” the leadership question is not, “How much have we already spent?” It is, “What did we learn that should change how we decide next time?”
Reward only delivery, and teams protect the plan. Reward clear evidence and well-reasoned revision, and teams surface weak assumptions before they become expensive commitments.
Leaders must make revision visible. Say when you changed your mind, what evidence changed it, and what the organization will do differently. If people only see successful decisions, they learn that looking right matters more than getting it right.
AI will accelerate execution. Organizations that outperform will make judgment visible, testable, and reusable, so they don’t pay to learn the same lesson twice.
This essay is part of Building Judgment: Leadership, AI, and Human Capability, a Substack exploring how organizations learn, decide, and adapt in an era of accelerating uncertainty.